Skip to content
LargeQuant Devices

Private quantitative compute, ready to run LargeQuant.

Integrated appliances for LQM inference, Quantitative Generative AI, private research and governed model-training workloads. Choose a device, buy online with Stripe, or talk to sales for institutional quantities and deployment planning.

USD product pricing. Import duties, VAT and other local taxes are not included. Product photography is an illustrative LargeQuant enclosure render; qualified component platforms determine the technical specification.
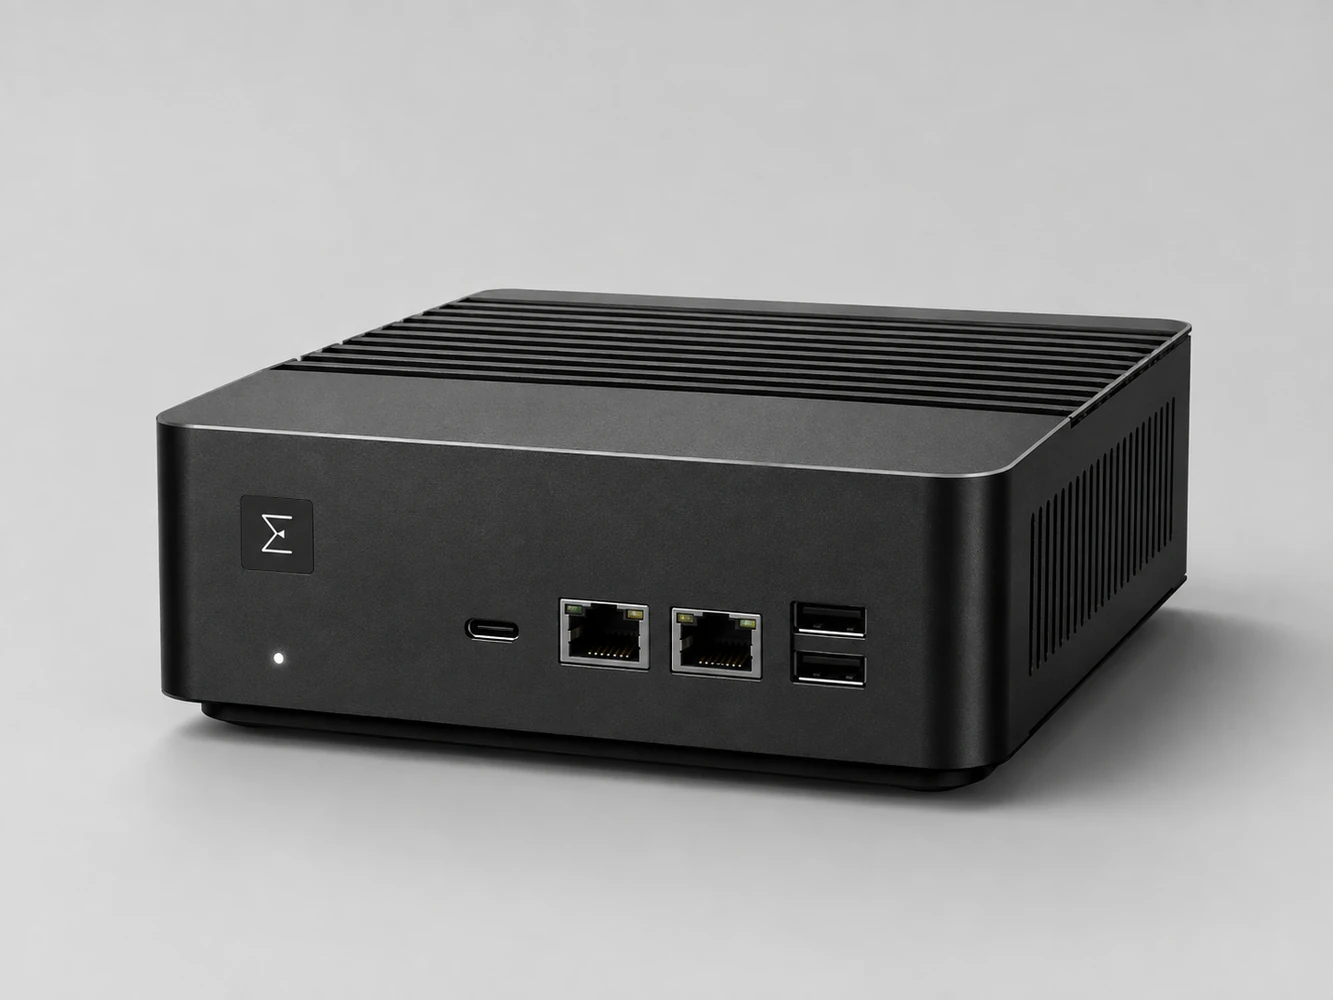
LQ Edge quantitative AI appliance
Compact edge Quantitative Generative AI appliance

LQ Edge

$1,593.98USD

A compact appliance for private LQM inference, telemetry, monitoring and governed quantitative signals close to the data source.

AI performance
Up to 67 TOPS in Super/MAXN mode
Compute module
NVIDIA Jetson Orin Nano 8 GB
GPU
NVIDIA Ampere architecture with Tensor Cores
Memory
8 GB LPDDR5
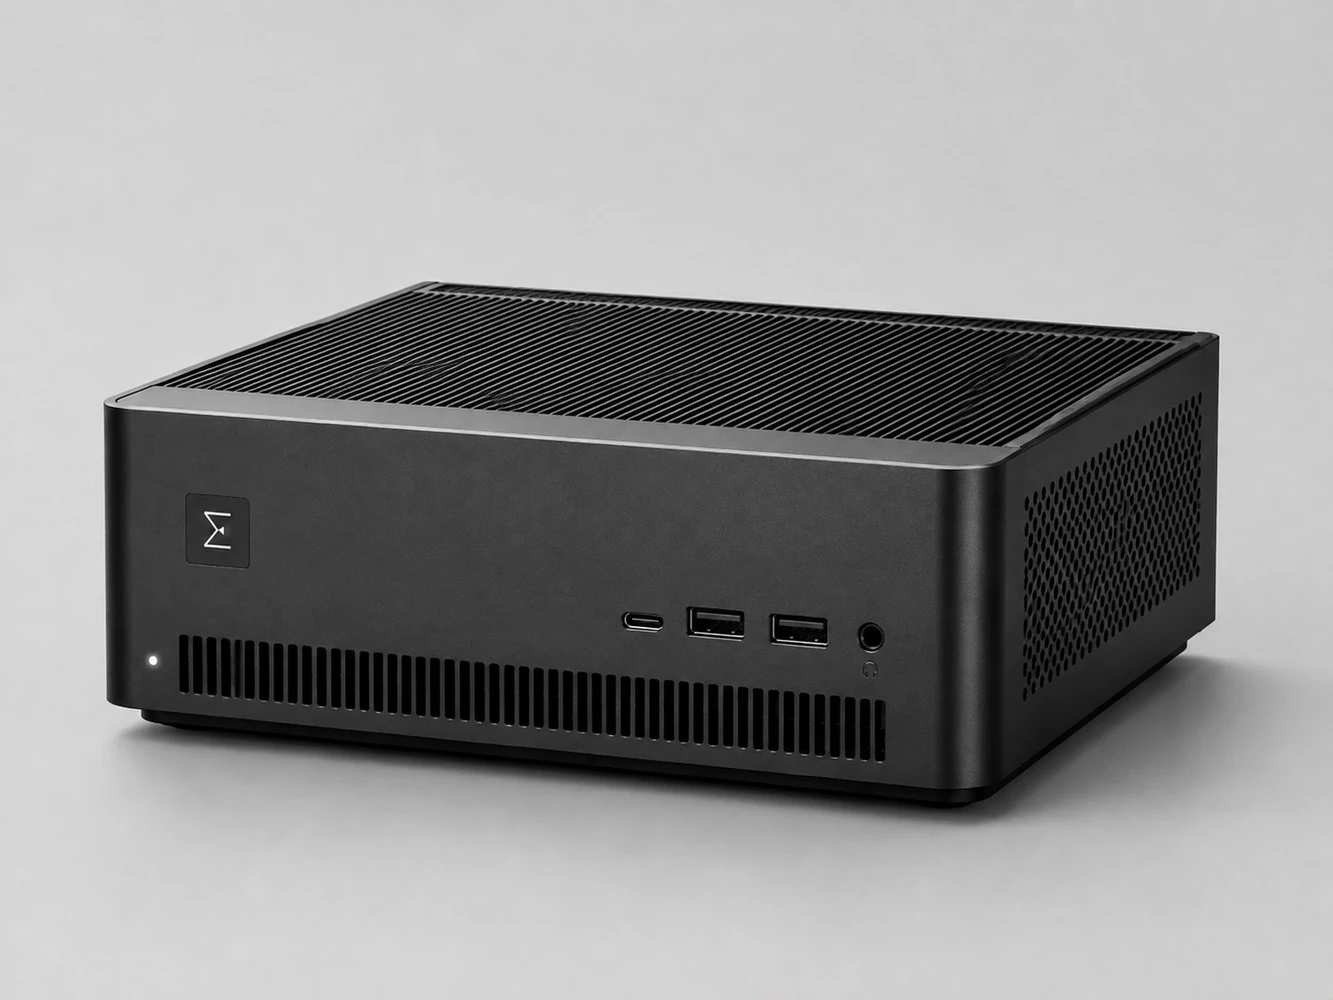
LQ Node One quantitative AI appliance
128 GB unified-memory quantitative AI workstation

LQ Node One

$7,438.00USD

A compact high-memory workstation for private datasets, Quantitative Generative AI, model experimentation, training and medium-to-large LQM inference.

Processor
AMD Ryzen AI Max+ 395, 16 cores / 32 threads, up to 5.1 GHz
Graphics
AMD Radeon 8060S, 40 GPU cores, up to 2.9 GHz
AI compute
Up to 50 TOPS NPU / up to 126 TOPS total platform AI compute
Memory
128 GB LPDDR5x-8000 unified memory
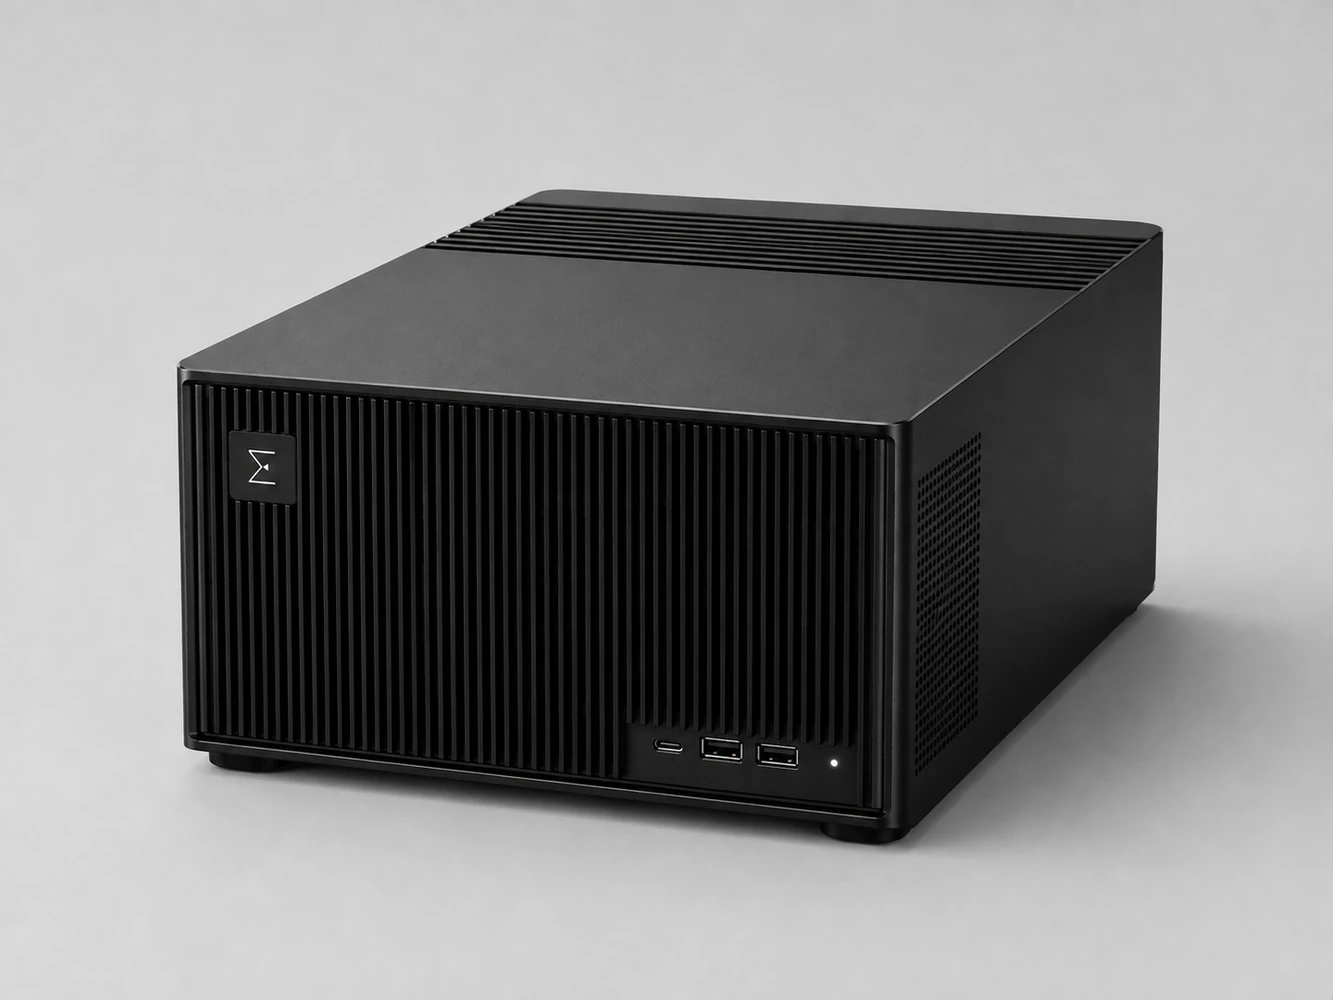
LQ Node Black quantitative AI appliance
Grace Blackwell desktop quantitative AI supercomputer

LQ Node Black

$9,398.00USD

A high-memory desktop appliance for larger local models, accelerated Foundry workloads, private quantitative research and high-capacity inference.

Superchip
NVIDIA GB10 Grace Blackwell
CPU
20-core Arm: 10× Cortex-X925 + 10× Cortex-A725
AI performance
Up to 1 PFLOP FP4
Memory
128 GB LPDDR5x coherent unified system memory
Device software

Hardware is the vessel. LargeQuant is the operating layer.

Runtime

Local LQM execution

Governed model registry, LQCP execution and LQEP evidence on the appliance.

Operations

Edge observability

Deployment identity, operational telemetry and synchronization to the institutional control plane.

Privacy

Keep sensitive data local

Run compatible quantitative workloads without requiring raw institutional data to leave the device.

Fleet architecture

From one node to a governed quantitative fleet.

Devices can operate as local inference or research nodes while the platform maintains model identity, evidence, deployment state and observability across the fleet.

01
Provision.
Register the device and runtime identity.
02
Deploy.
Send governed models to eligible devices.
03
Observe.
Capture evidence, latency and operational state.
04
Control.
Update, retire or roll back models through governance.